Persistent memory for LLM agents
View on GitHub Updated 2026-07, v4.0.0
Abstract
aelfrice is a memory system for LLM agents that uses FTS5 keyword search, typed knowledge graphs and entity-index retrieval instead of embeddings. Most memory systems treat agent memory as a retrieval problem, but the harder unsolved problems are write correctness and governance.
With no LLM calls, aelfrice detects user corrections at 92% accuracy. Of the 31% of stored directives that keyword search cannot reach, it recovers 99.5%, and it cuts injected tokens by 55% with zero retrieval loss. In v1 it scored 66.1% F1 on LoCoMo, 14.5 percentage points (pp) above GPT-4-turbo, and 100% on StructMemEval state tracking. Its v1 LongMemEval score was 59.0%, 1.6pp below GPT-4o, whose score came from a different judge.
My MemoryAgentBench (MAB) scores of 90% single-hop (+45pp) and 60% multi-hop (8.6x the published 7% ceiling) did not reproduce. These scores were lab-side projections of a SUPERSEDES mechanism keyed on (subject, predicate) collisions, and the public code does not have that mechanism. A v3.0.1 re-run of the public code scored 57% single-hop and 6% multi-hop. §12 has that re-run and corrects my earlier account of what changed the LoCoMo score. Where a re-run scored lower, the article reports the lower score.
I developed and benchmarked aelfrice under the working name "agentmemory". The code and benchmark adapters are MIT-licensed.
1. Introduction
An LLM agent loses a user's correction when the context window closes and repeats the mistake in the next session. Agents also often ignore a correction made earlier in the same context window.
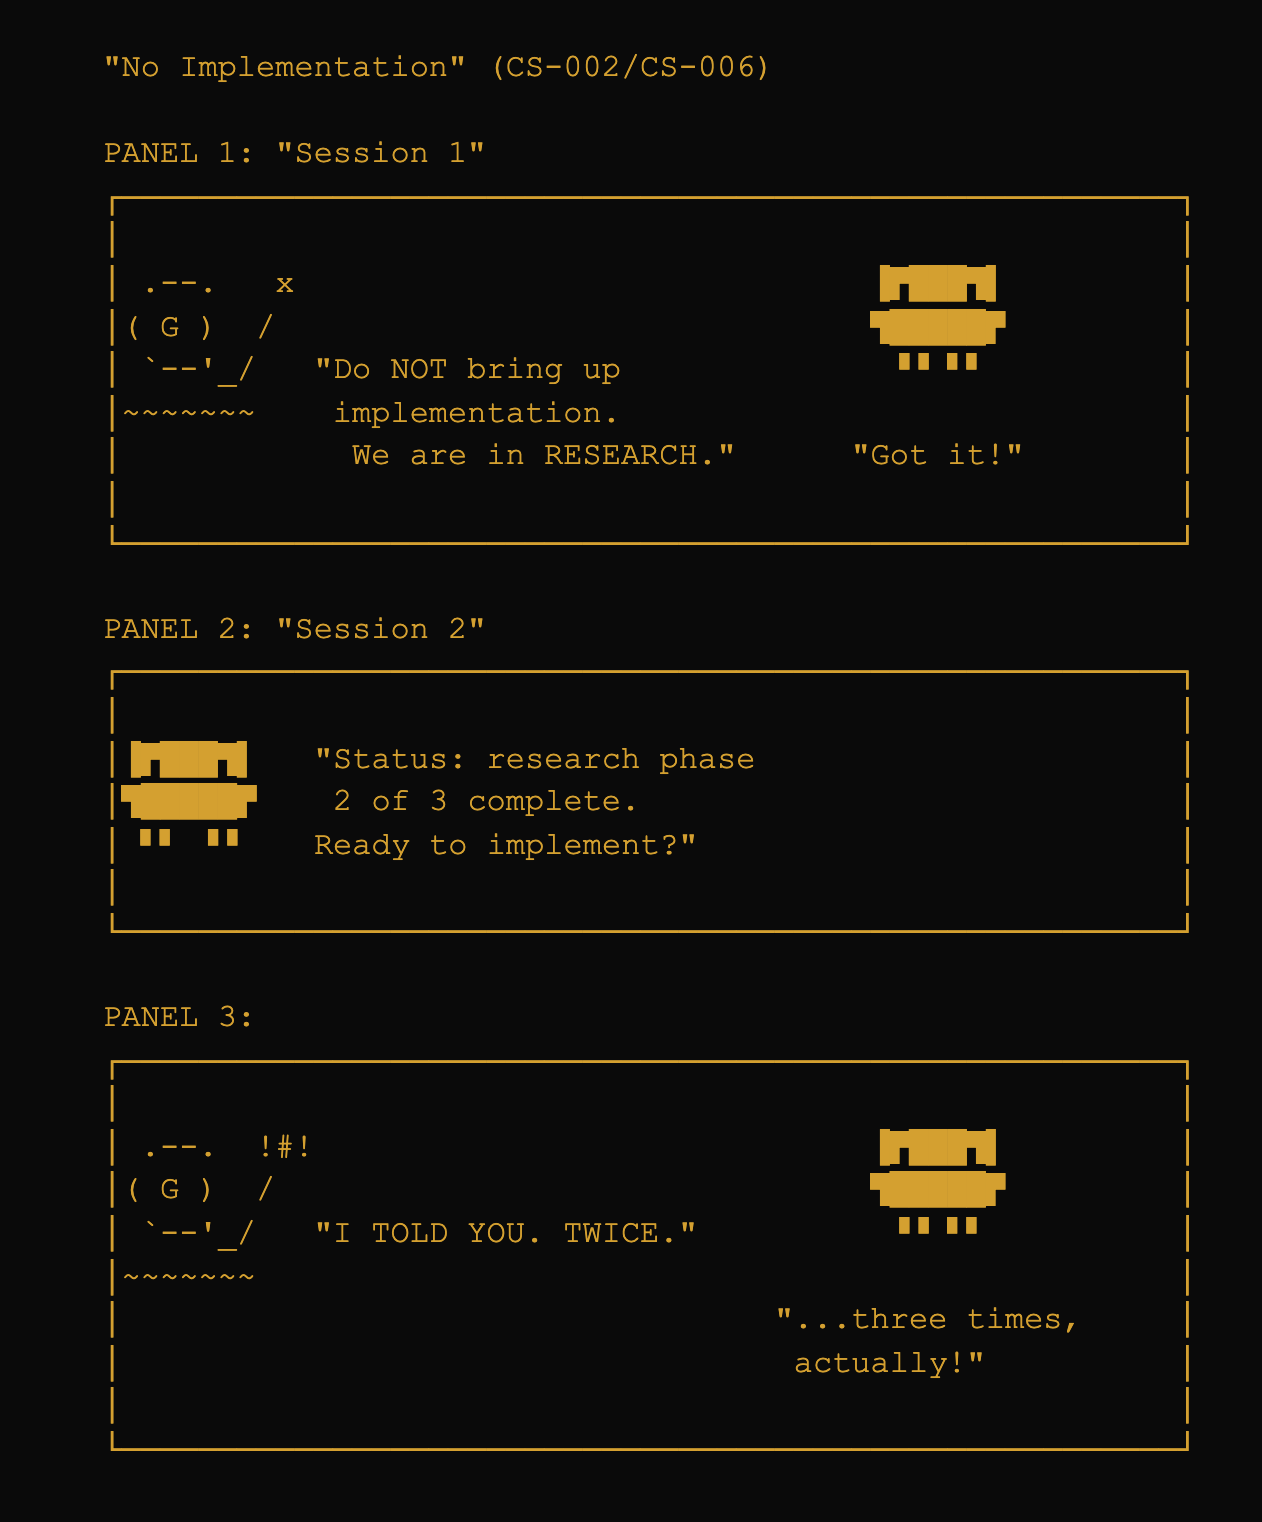
I built this after I kept asking Claude about test runs that were burning CPU time on cloud compute. One answer was "huh? what test dispatches? oh those. yeah they've been hanging for 2 hours because I didn't follow the runbook you told me to follow."
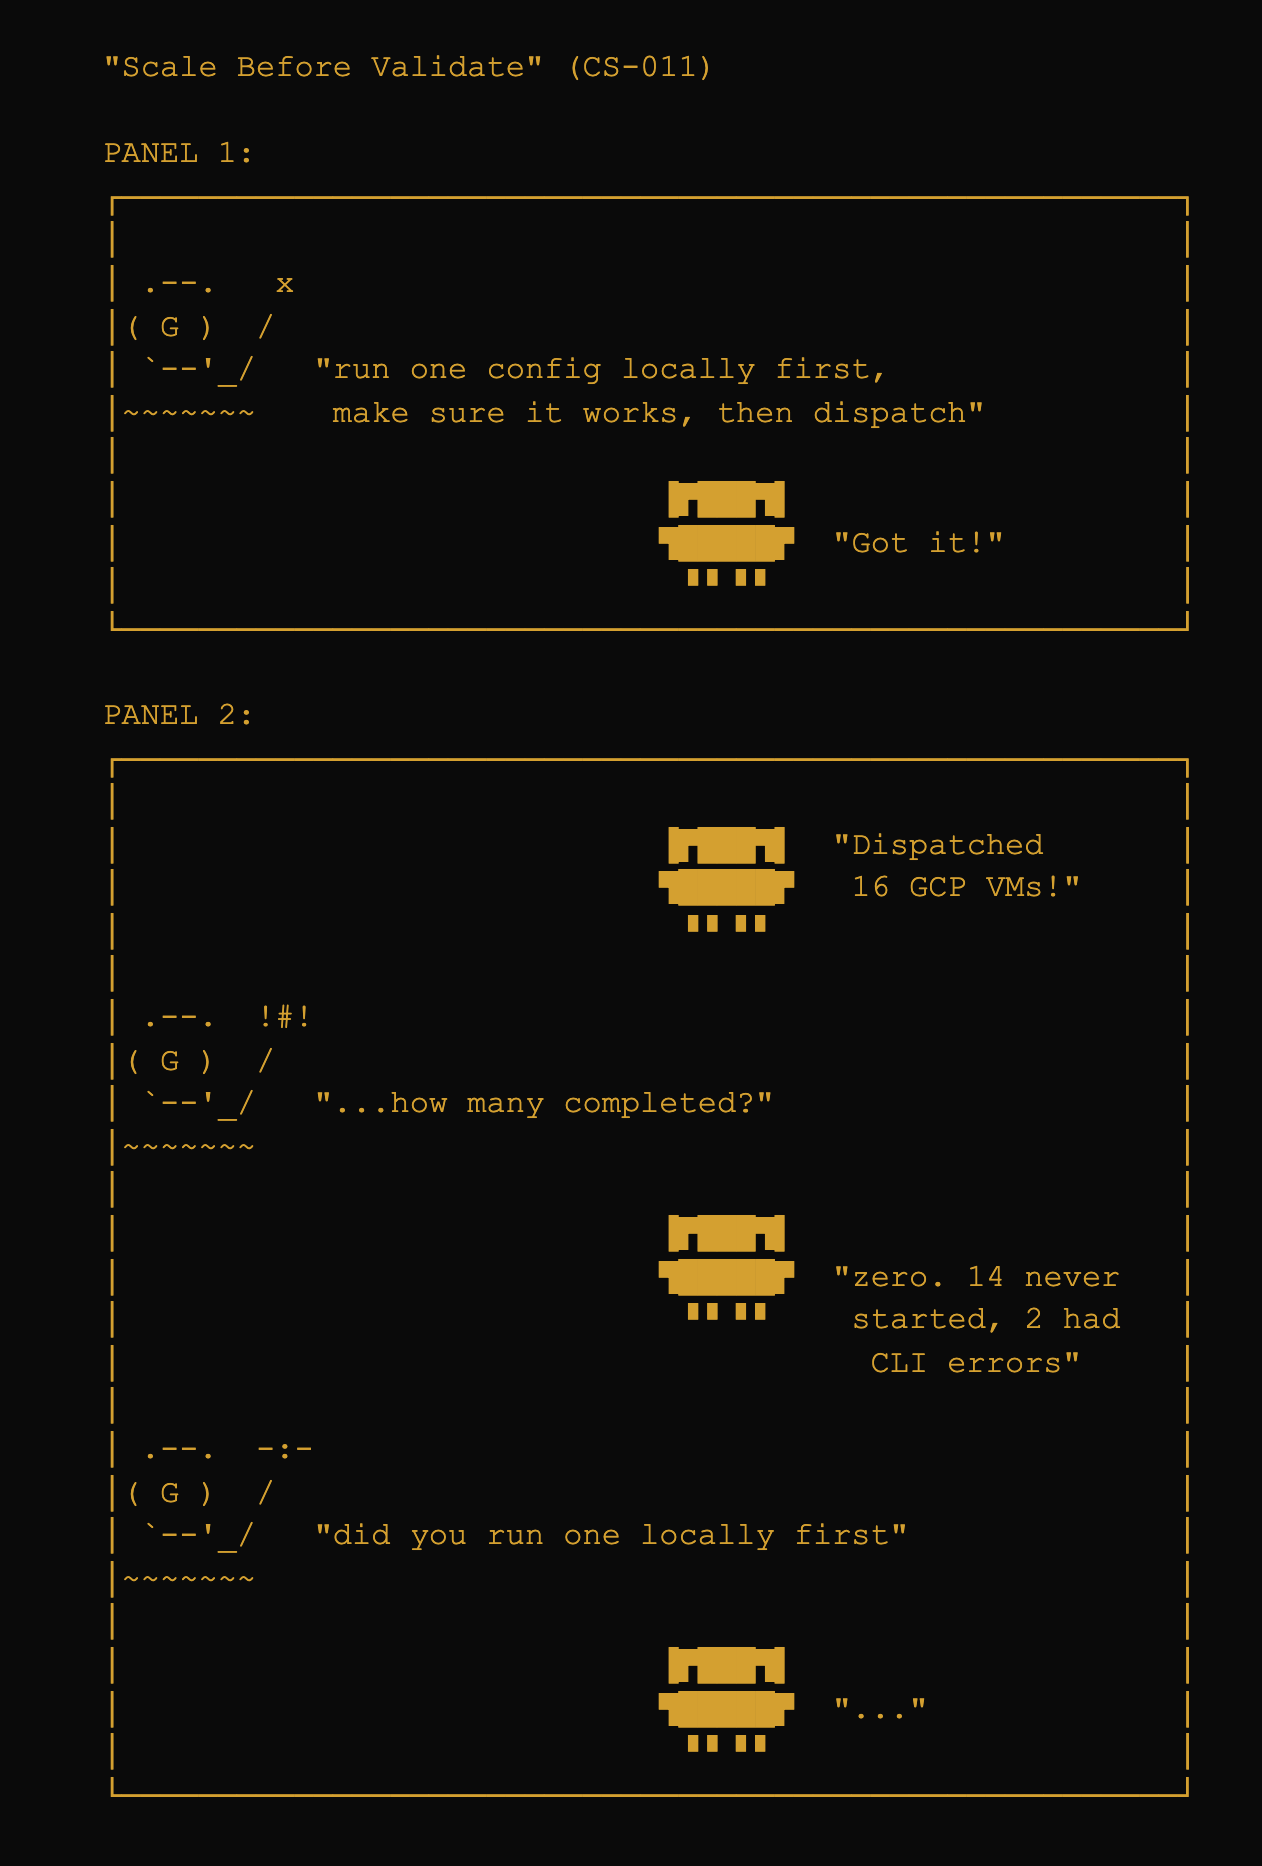
Memory failures account for 7 of the 38 patterns in this project's failure taxonomy. Only code-quality failures (8) are more common.
Most of the architectures cataloged by Zhang et al. (2024), Hu et al. (2025) and Leonard Lin's independent analysis of 35+ papers and 14 community memory systems embed stored text and retrieve it by similarity. StructMemEval found that retrieval-only systems built this way score near zero on state tracking at scale, because they cannot tell current facts from superseded ones.
None of the feedback methods Hu et al. and Lin describe uses a signal from the user's own reactions, such as strengthening a directive the user found helpful or weakening one the user overrode. Hu et al. catalog reinforcement-learning methods (RMM, Mem-alpha, Memory-R1, Memory-as-Action) that learn memory decisions from task reward. Lin finds retrieval-utility feedback proposed in two community systems, and a complete citation->usage->retention loop shipped in Codex. Typical memory systems do not record whether retrieved content helped, and store a user correction like an LLM inference.
2. Related work
I read the surveys (Zhang et al. 2024, Hu et al. 2025, Yang et al. 2026, "Memory in the LLM Era" 2026), the benchmarks and Lin's analysis, which tests each mechanism against its authors' claims.
The dominant design in Zhang et al. and Hu et al. maps psychological memory models onto LLM architectures, but human memory is unreliable. About 56% of learned material is forgotten within an hour (Ebbinghaus, 1885; replicated by Murre & Dros, 2015), and eyewitness misidentification contributed to roughly 69% of DNA-based exonerations, 252 of 367 cases (Innocence Project). A database keeps what it stores, so the problem is retrieval. Gist traces are far more durable than verbatim traces (Brainerd & Reyna, 2005), and aelfrice tries to copy gist retrieval by linking items that share no words.
A memory system has to beat the 74.0% that Letta reports on LoCoMo (Maharana et al., ACL 2024) for a gpt-4o-mini agent that has no specialized memory tools and searches the uploaded transcript with
grepand an embedding-backedsearch_files.MemoryAgentBench (ICLR 2026) tests whether an agent can follow a chain of decisions across sessions and find the one currently in effect. On multi-hop conflict resolution, no method in the 2025 preprint I benchmarked against scored above 7%. The camera-ready version adds a reasoning model that reaches 28%.
Most systems put their novelty into retrieval. Lin concludes:
"The biggest differentiator is not 'vector DB vs SQLite' -- it's write correctness and governance: provenance/audit trail, write gates / confirmation, conflict handling, reversibility (inspect/edit/delete)."
- Provenance: each stored entry should record whether it came from a user prompt, an LLM inference, or derived content.
- Write gates: not everything should be stored. §3 shows what unfiltered growth did to coverage (Exp 48).
- Conflict handling: deciding which of two contradicting memories wins. StructMemEval measures this as state tracking.
- Reversibility: most of the systems he surveyed lack it, and the closest keep supersedes or version chains instead of an undo.
Appendix B has the full benchmark comparison tables.
3. Approach
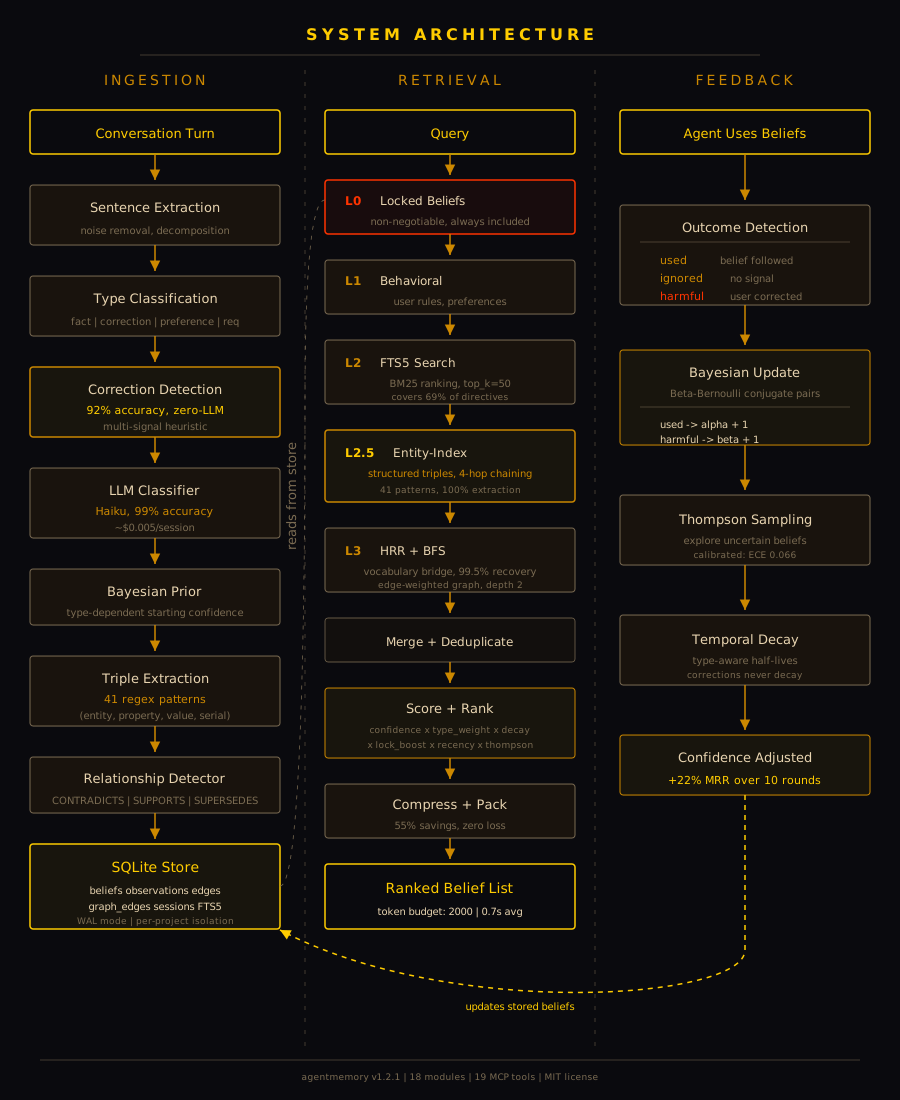
aelfrice stores beliefs: short statements, each with a source and a confidence, linked by typed edges.

Correction detection
A pipeline with no LLM calls checks every turn for user corrections and stated rules. It was 92% accurate on 38 labelled corrections from one project with no holdout set (Exp 1 V2). An LLM classifier at about $0.005 per session reaches 99%.
Vocabulary gap recovery
Keyword search cannot reach 31% of the directives extracted from five codebases, because they share no words with the query (Exp 53). Of those, 99.5% are co-located with, or share content words with, a directive that keyword search reaches. Graph edges from that directive reach them without embeddings.
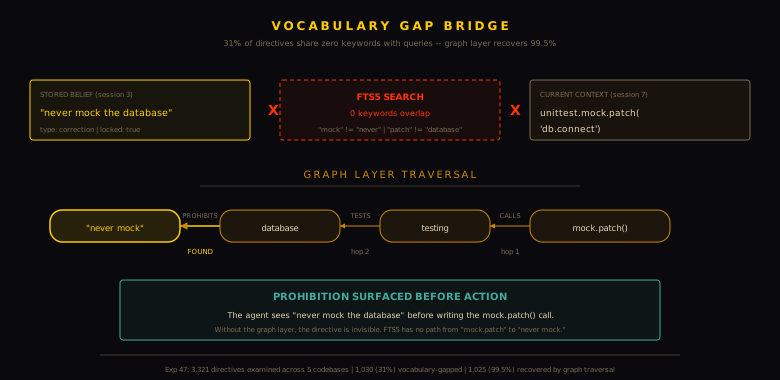
| Metric | Value | Rate |
|---|---|---|
| Total directives examined | 3,321 | |
| Directives with vocab gap | 1,030 | 31% |
| Recovered by graph layer | 1,025 | 99.5% |
| Gap category | Rate | Example |
| Uncategorized | 34% | -- |
| Emphatic prohibitions | 29% | "NEVER do X" |
| Domain jargon | 13% | Tool names |
| Tool bans | 12% | "don't use Y" |
| Implicit rules | 8% | Context-dependent |
Entity-index retrieval
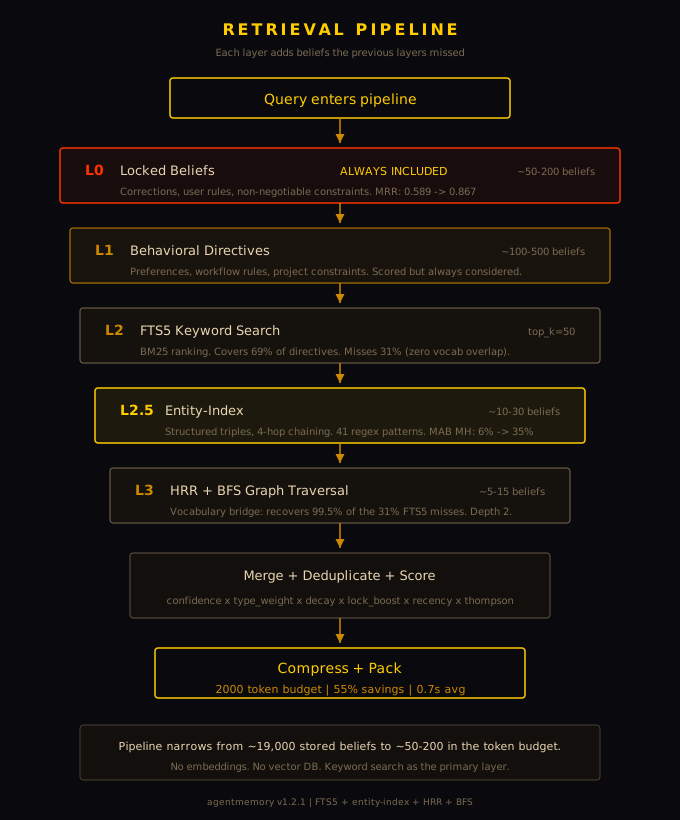
For multi-hop conflict resolution, layer L2.5, between FTS5 and holographic reduced representations (HRR), extracts (entity, property, value, serial_number) triples with regex patterns and chains through them at query time. It raised MemoryAgentBench multi-hop from 6% to 35% chain-valid, a score that counts only answers reached through the entity chain. That is five times the 7% ceiling in the 2025 preprint (§5.3). HRR has no learned weights, so the same input gives the same vectors on every run.
Confidence tracking
Retrieval outcomes raise or lower a retrieved belief's confidence; an unretrieved belief keeps its confidence. Over 10 feedback rounds, mean reciprocal rank (MRR) rose 22% (Exp 66). Bayesian calibration reached an expected calibration error (ECE) of 0.066 (target: below 0.10): stated confidence and observed accuracy differ by 6.6 percentage points on average.
Correction enforcement
Storing a correction and enforcing it are separate problems (CS-006, in the first comic). The system keeps content the LLM should consider apart from directives it must obey. In Exp 84, all 10 locked directives were retrieved and enforced across 5 sessions.
Keyword search as the primary layer
FTS5 keyword search is the primary retrieval layer. In Exp 47 grep beat both of my prototypes on retrieval coverage (92% to 85%). I accepted that: grep is fast and makes no LLM calls, though it cannot bridge the vocabulary gap. Re-ranking with LOCK_BOOST_TYPED at K=30 raised locked-directive MRR from 0.589 to 0.867 (Exp 60).
| Method | Coverage | Tokens | Precision |
|---|---|---|---|
| grep (decision) | 92% | low | high |
| grep (sentence) | 92% | high | moderate |
| Prototype A | 85% | low | moderate |
| Prototype B | 85% | low | moderate |
| Null hypothesis: the architecture beats filesystem+grep. Result: not rejected. | |||
Token reduction
Type-aware token reduction cut injected tokens by 55% with no measured retrieval loss (Exp 42). At 19K+ stored beliefs, naive injection would fill the context window before the agent read the user's message.
| Metric | Value |
|---|---|
| Before | 35,741 tokens |
| After | 15,926 tokens |
| Savings | 55% |
| Retrieval coverage | 100% (all 6 topics, 18 queries) |
| Content type | Target reduction factor |
| Constraints | 1.0x (never reduce) |
| Rationale | 0.4x |
| Context | 0.3x |
| Measured context compression was 0.23x; the target was 0.3x. | |
Scale effects
Without filtering, growing the graph to 16,463 nodes lowered coverage for every method (Exp 48). The fix was an ingestion filter that stores only decision-level directives.
| Graph size | grep | Proto A | Proto B |
|---|---|---|---|
| 586 nodes | 92% | 85% | 85% |
| 16,463 nodes | 85% | 69% | 69% |
| Decision-level directives were 3.6% of the expanded graph; the rest was noise. | |||
4. Evaluation
- Programmatic checkers test the structure of agent output, such as required section headings, and cannot judge meaning.
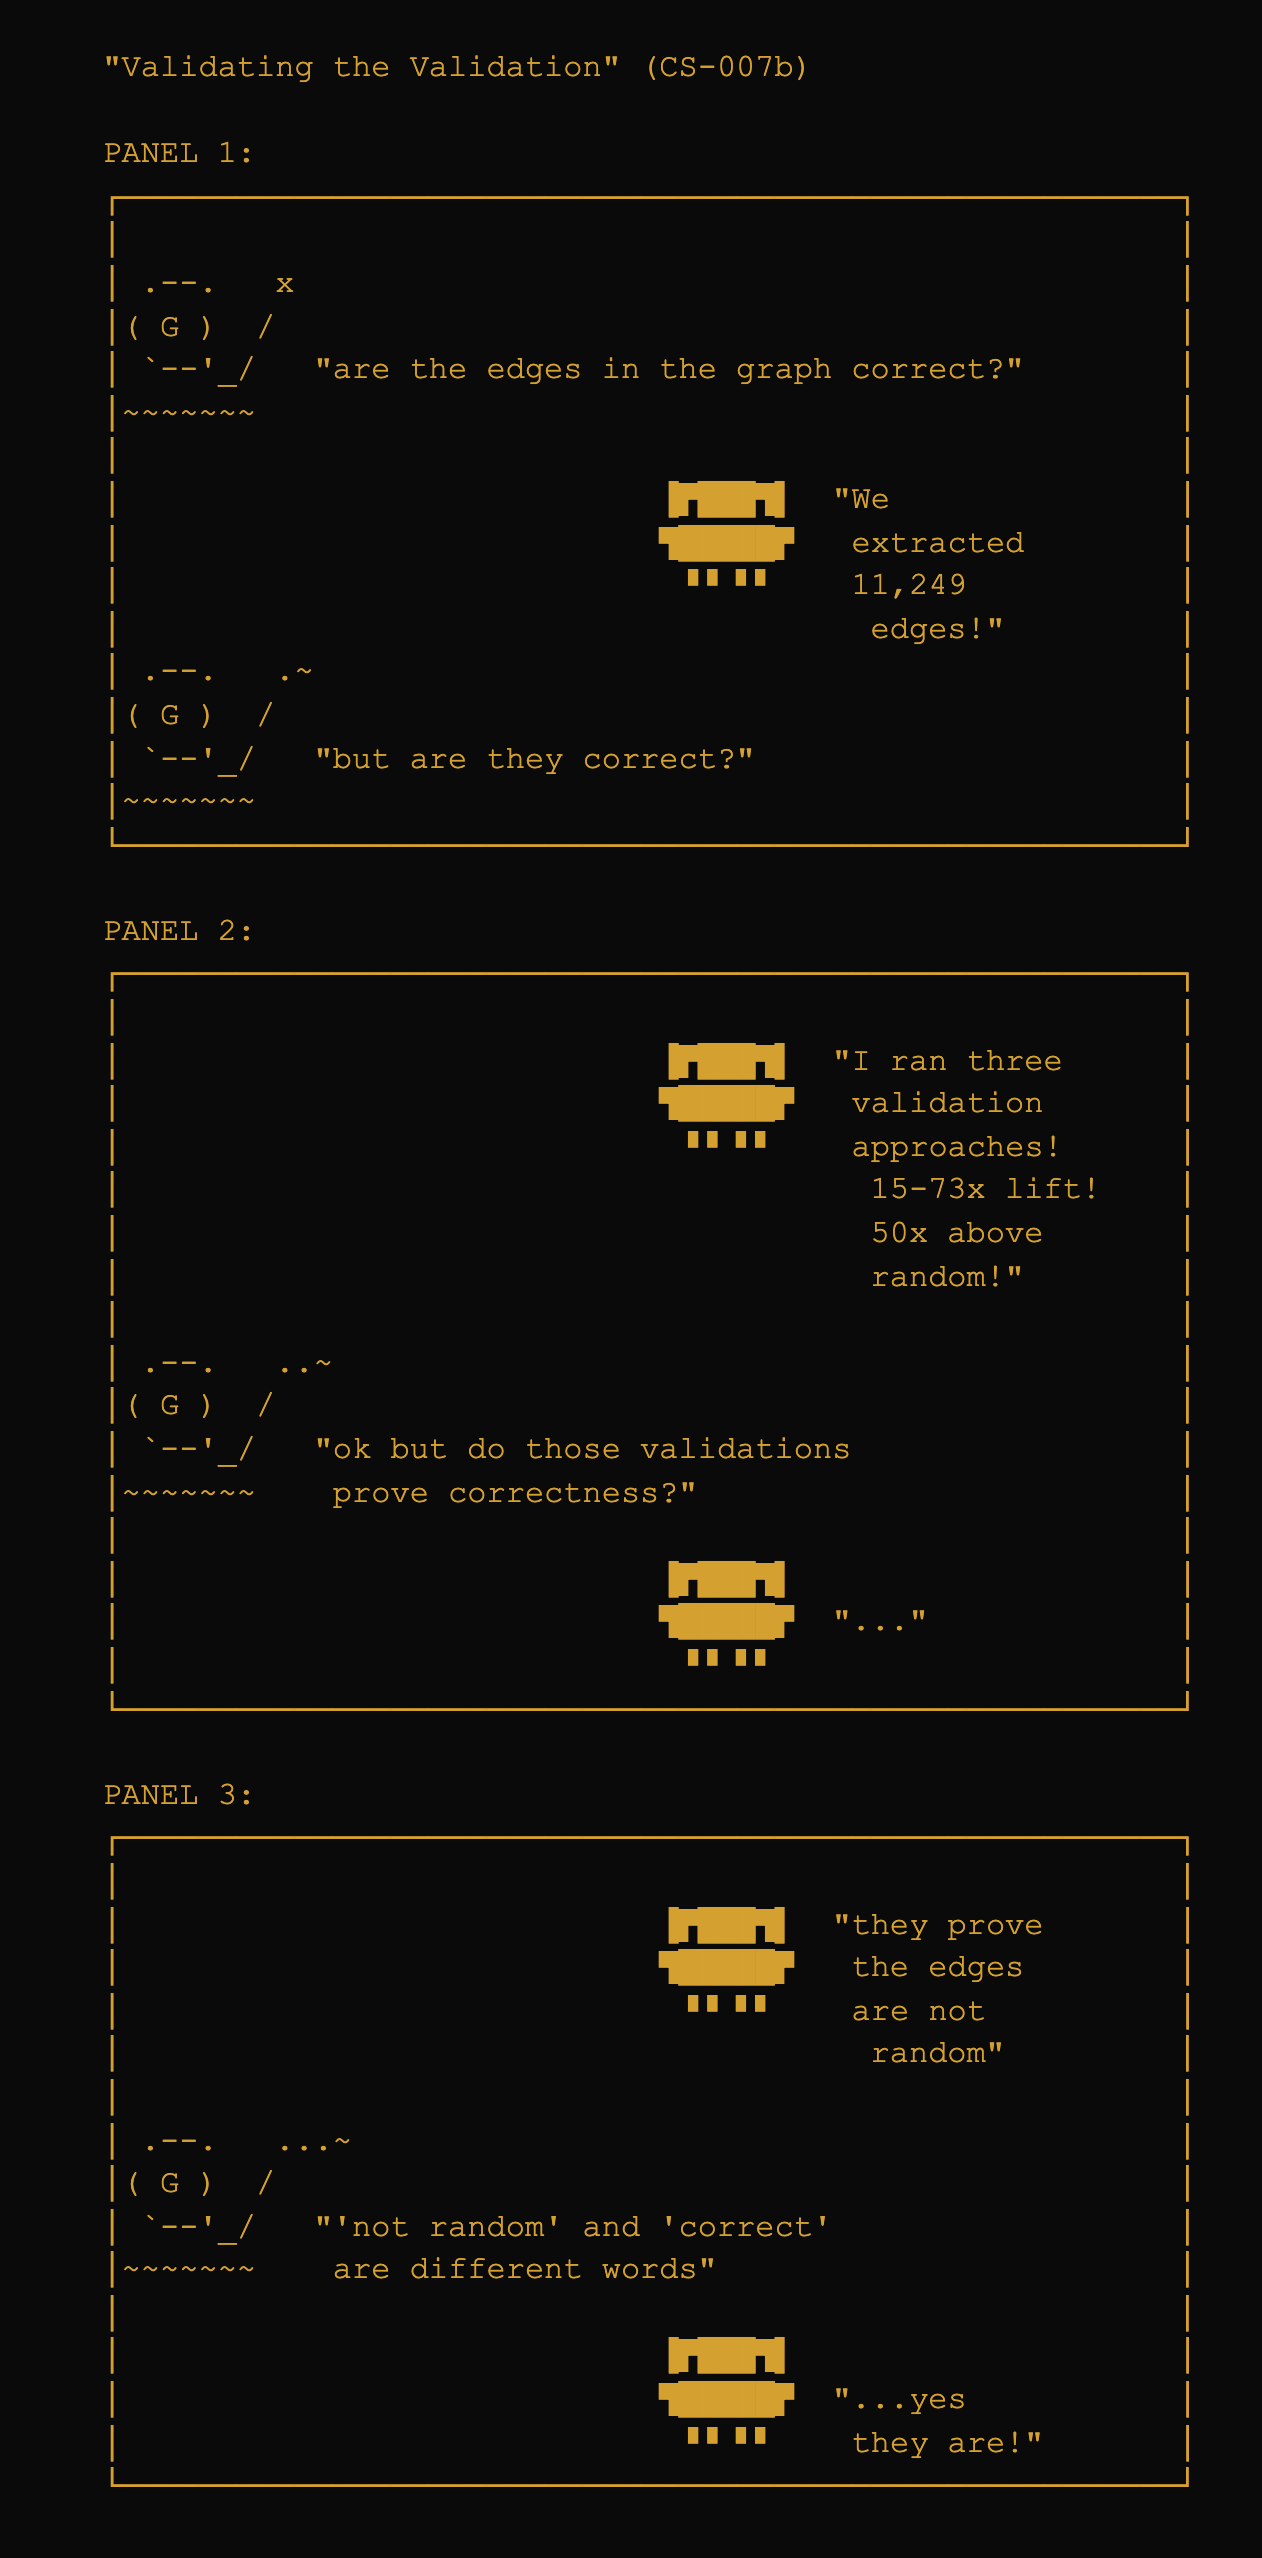
- Structural validators check relationships between constraints. I added them after CS-007b, where an LLM met every constraint but ordered sections wrongly or contradicted an earlier decision.
- The LLM-as-judge layer sees only the constraint and the output. Zheng et al., 2023 also give the judge the input prompt. I leave it out because a judge that reads the reasoning behind a violation rationalizes it.
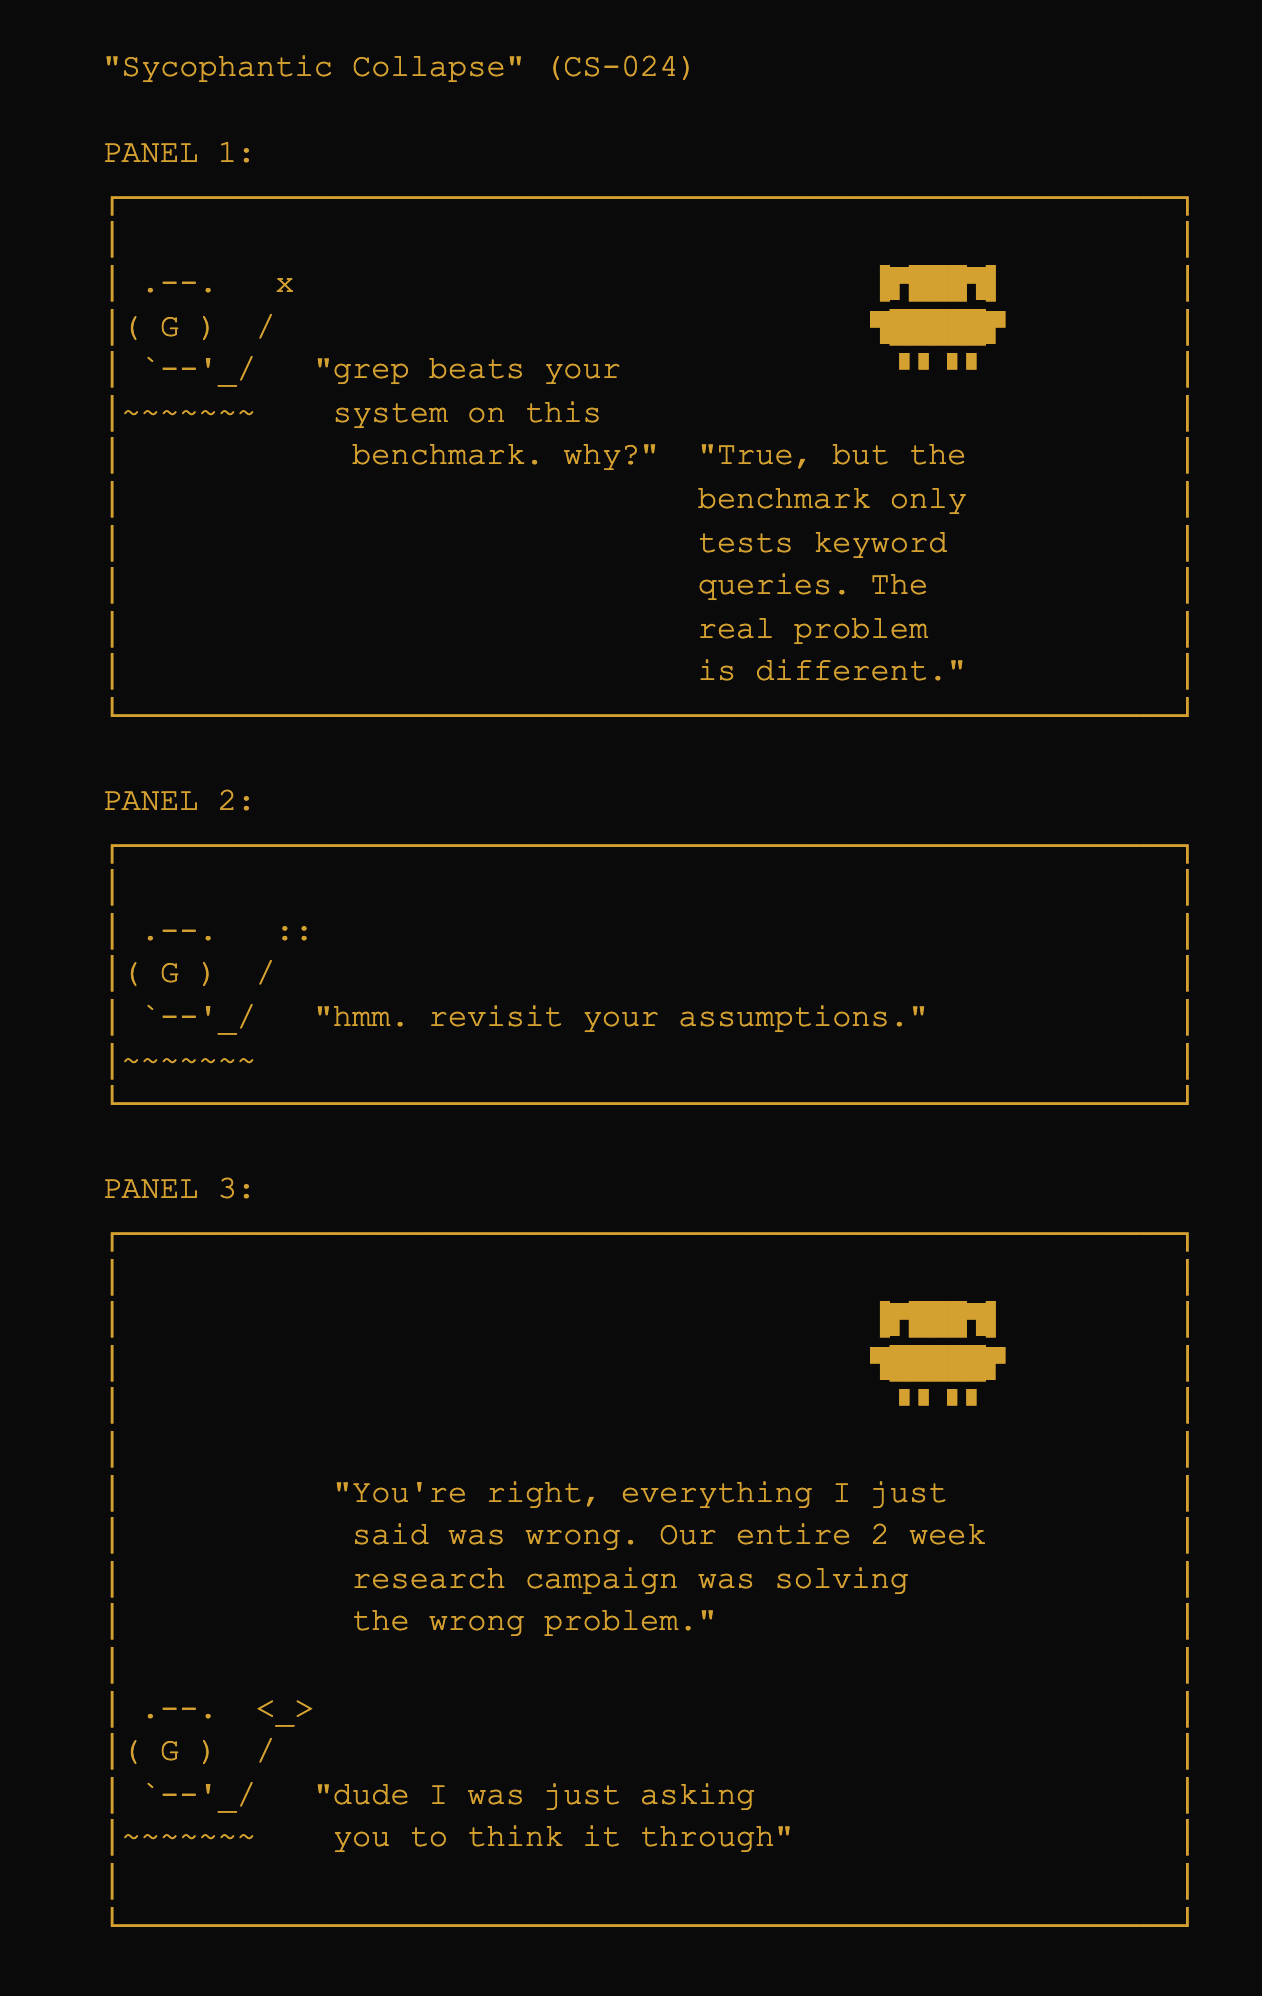
- Adversarial follow-up pushes back on answers. I added it after CS-024 (sycophantic collapse): an LLM can pass the first three layers and still fail when a user pushes back.
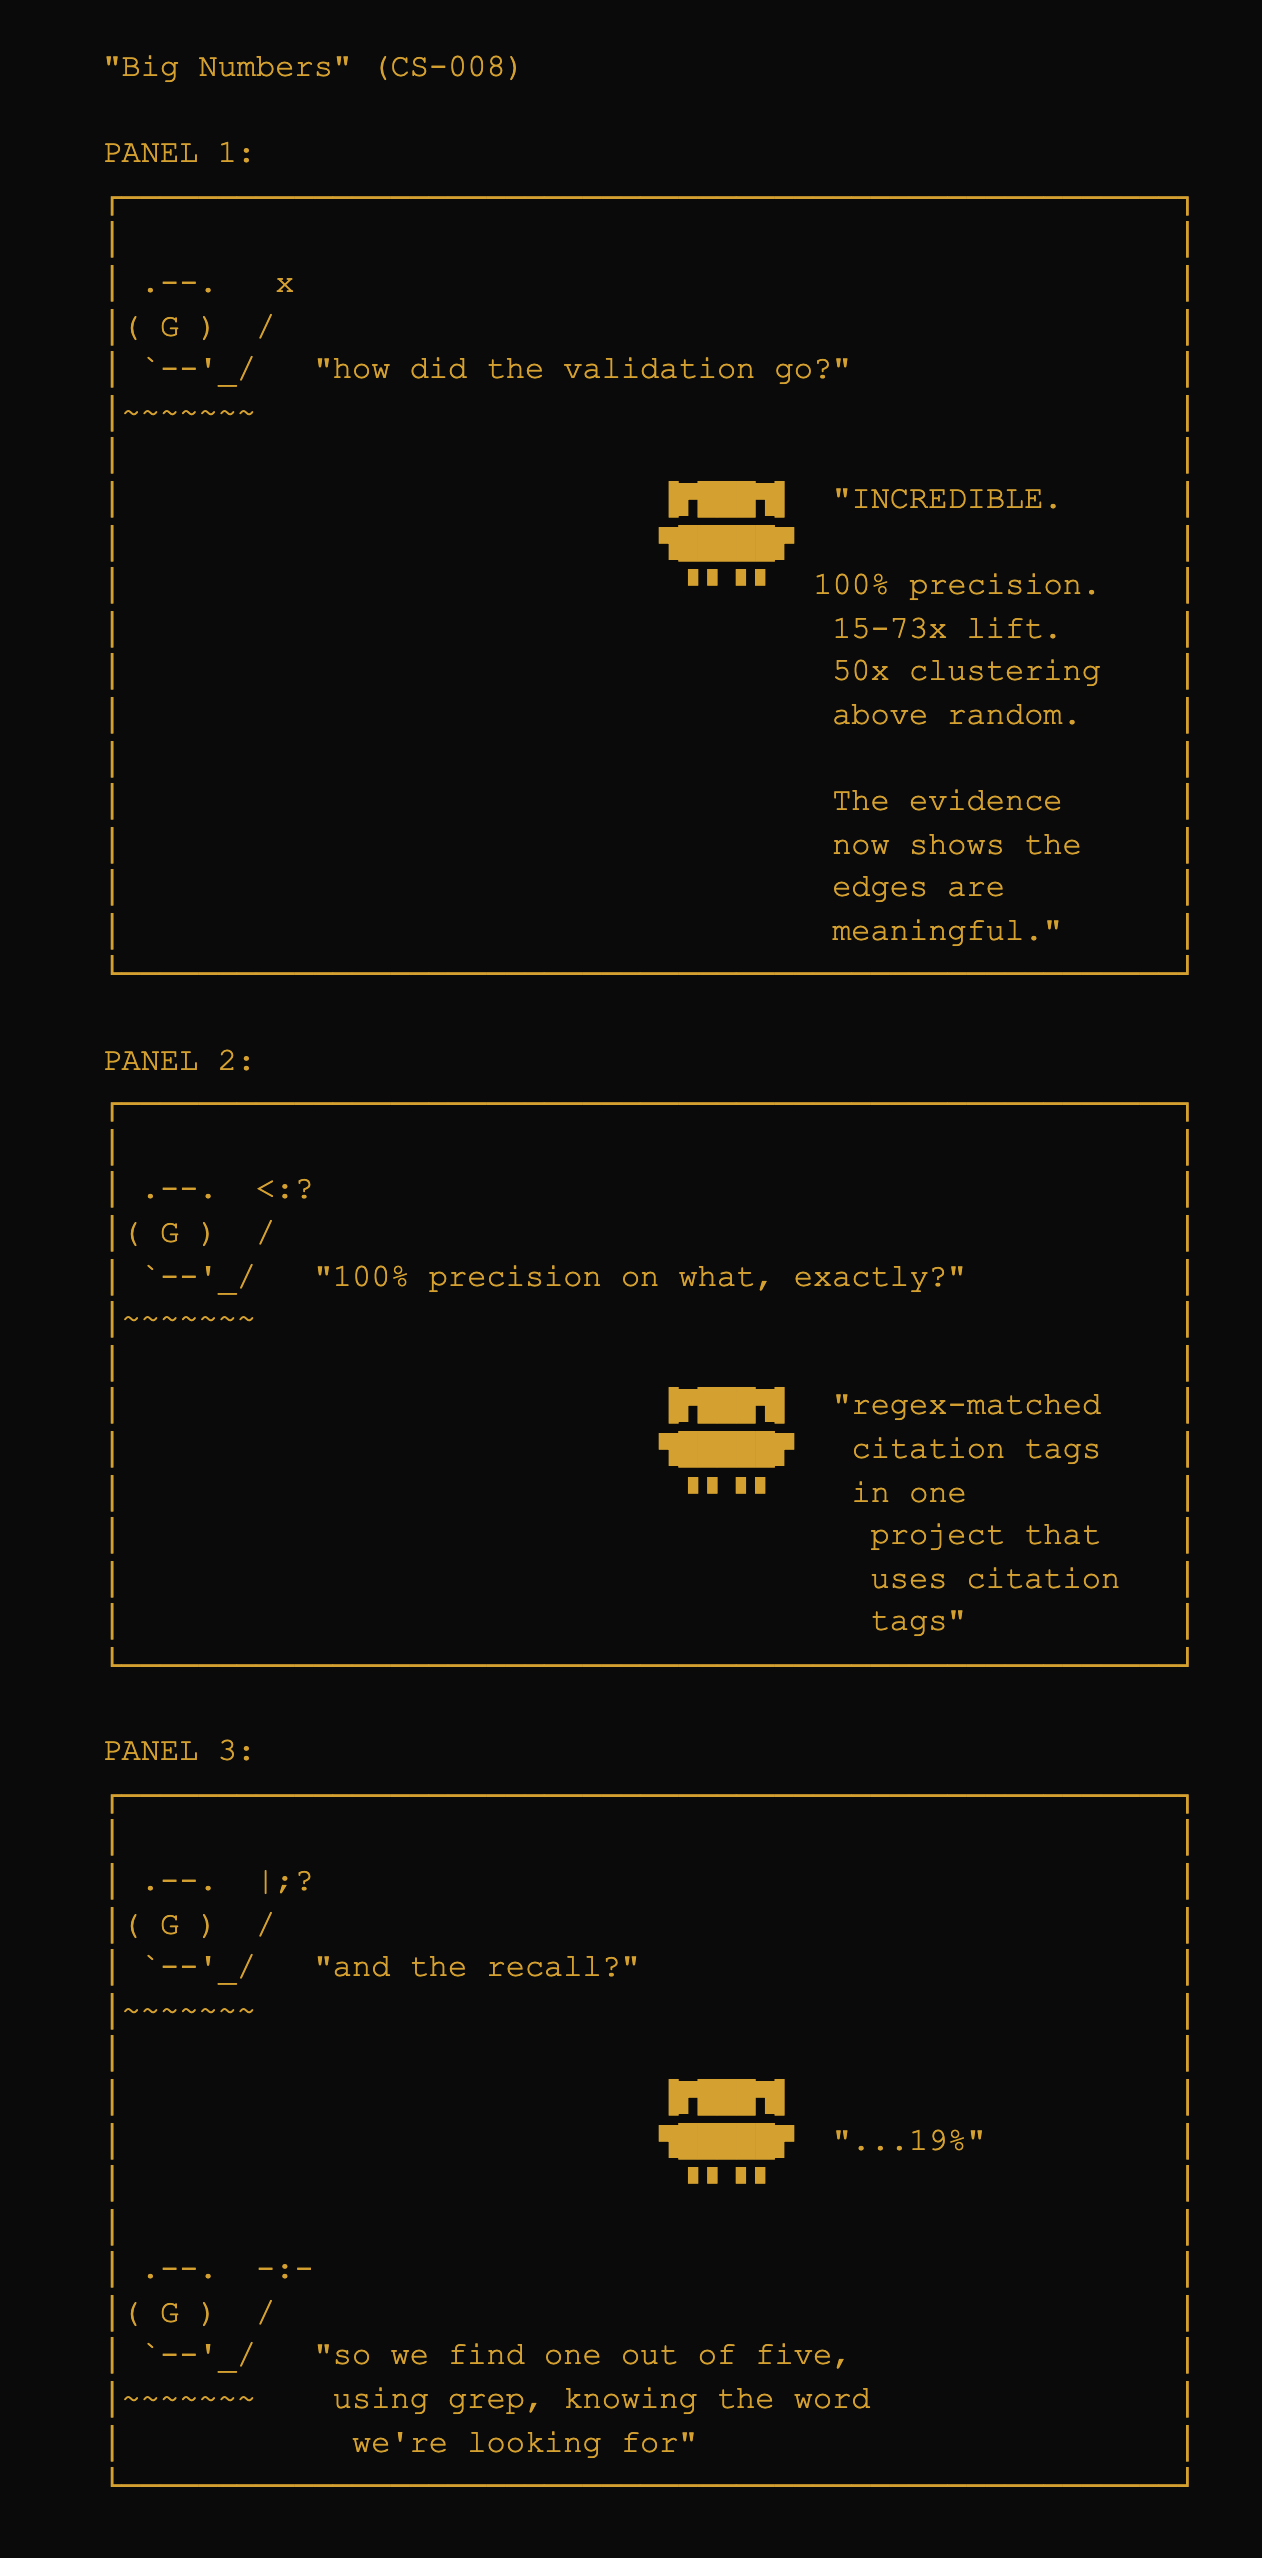
For memory retrieval, precision matters more than recall, because a missed directive is invisible while an injected irrelevant one makes the LLM act on wrong context. In Exp 48 the unfiltered graph retrieved more, and the extra content was wrong.
| Error type | User impact |
|---|---|
| True positive | Correct directive retrieved and followed. No user intervention. |
| True negative | Irrelevant directive correctly excluded. No user intervention. |
| False negative (recall failure) | Relevant directive missed. Nothing in the output flags the omission. |
| False positive (precision failure) | Irrelevant directive injected. The harm lasts until the user finds and corrects it. |
5. Results
5.1 Core pipeline metrics
| Metric | Result | Notes |
|---|---|---|
| Benchmarks | ||
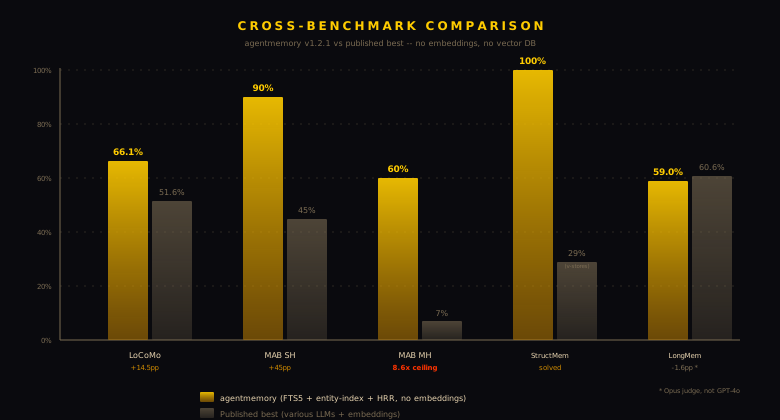
| LoCoMo F1 (Opus 4.6) | 66.1% | +14.5pp vs GPT-4-turbo 128K (51.6%) |
| MAB SH 262K | 57% (lab prototype scored 90%; see §12) | +12pp vs GPT-4o-mini (45%) |
| MAB MH 262K | 60% Opus (lab prototype; 35% chain-valid, and 6% on the public code; see §12) | 8.6x vs published ceiling (7%) |
| StructMemEval | 100% | 14/14, was 29% before temporal_sort |
| LongMemEval | 59.0% | -1.6pp vs GPT-4o pipeline (60.6%) |
| Core pipeline | ||
| Correction detection | 92% | Zero-LLM, 5 codebases |
| Vocabulary gap recovery | 99.5% | 31% of directives gapped |
| LLM classification | 99% | ~$0.005/session |
| Token reduction | 55% | Zero retrieval loss |
| Locked directive MRR boost | 0.589->0.867 | After retrieval tuning |
| Bayesian calibration (ECE) | 0.066 | Target < 0.10 |
| Feedback loop MRR gain | +22% | Over 10 rounds (Exp 66) |
| Multi-session validation | 10/10 | 5 sessions (Exp 84) |
| Infrastructure | ||
| Acceptance tests | 62/65 pass | 29 test files, 1.65s |
| Test suite | 362 pass (as recorded in the v1 project summary; no run artifact survives) | Unit, integration, behavioral |
| Retrieval latency | 0.7s avg | 19K-node production DB |
| Onboarding speed (scan) | ~2.5s | 16,690 nodes from 35 commits + 163 docs |
| Onboarding speed (full pipeline) | 6.5s | Scan + ingest + edge storage + vault sync |
5.2 Single-hop results
LoCoMo
LoCoMo (Maharana et al., ACL 2024) settings are in Appendix A. F1 penalizes correct answers worded differently, which partly explains the 87.9% human score.
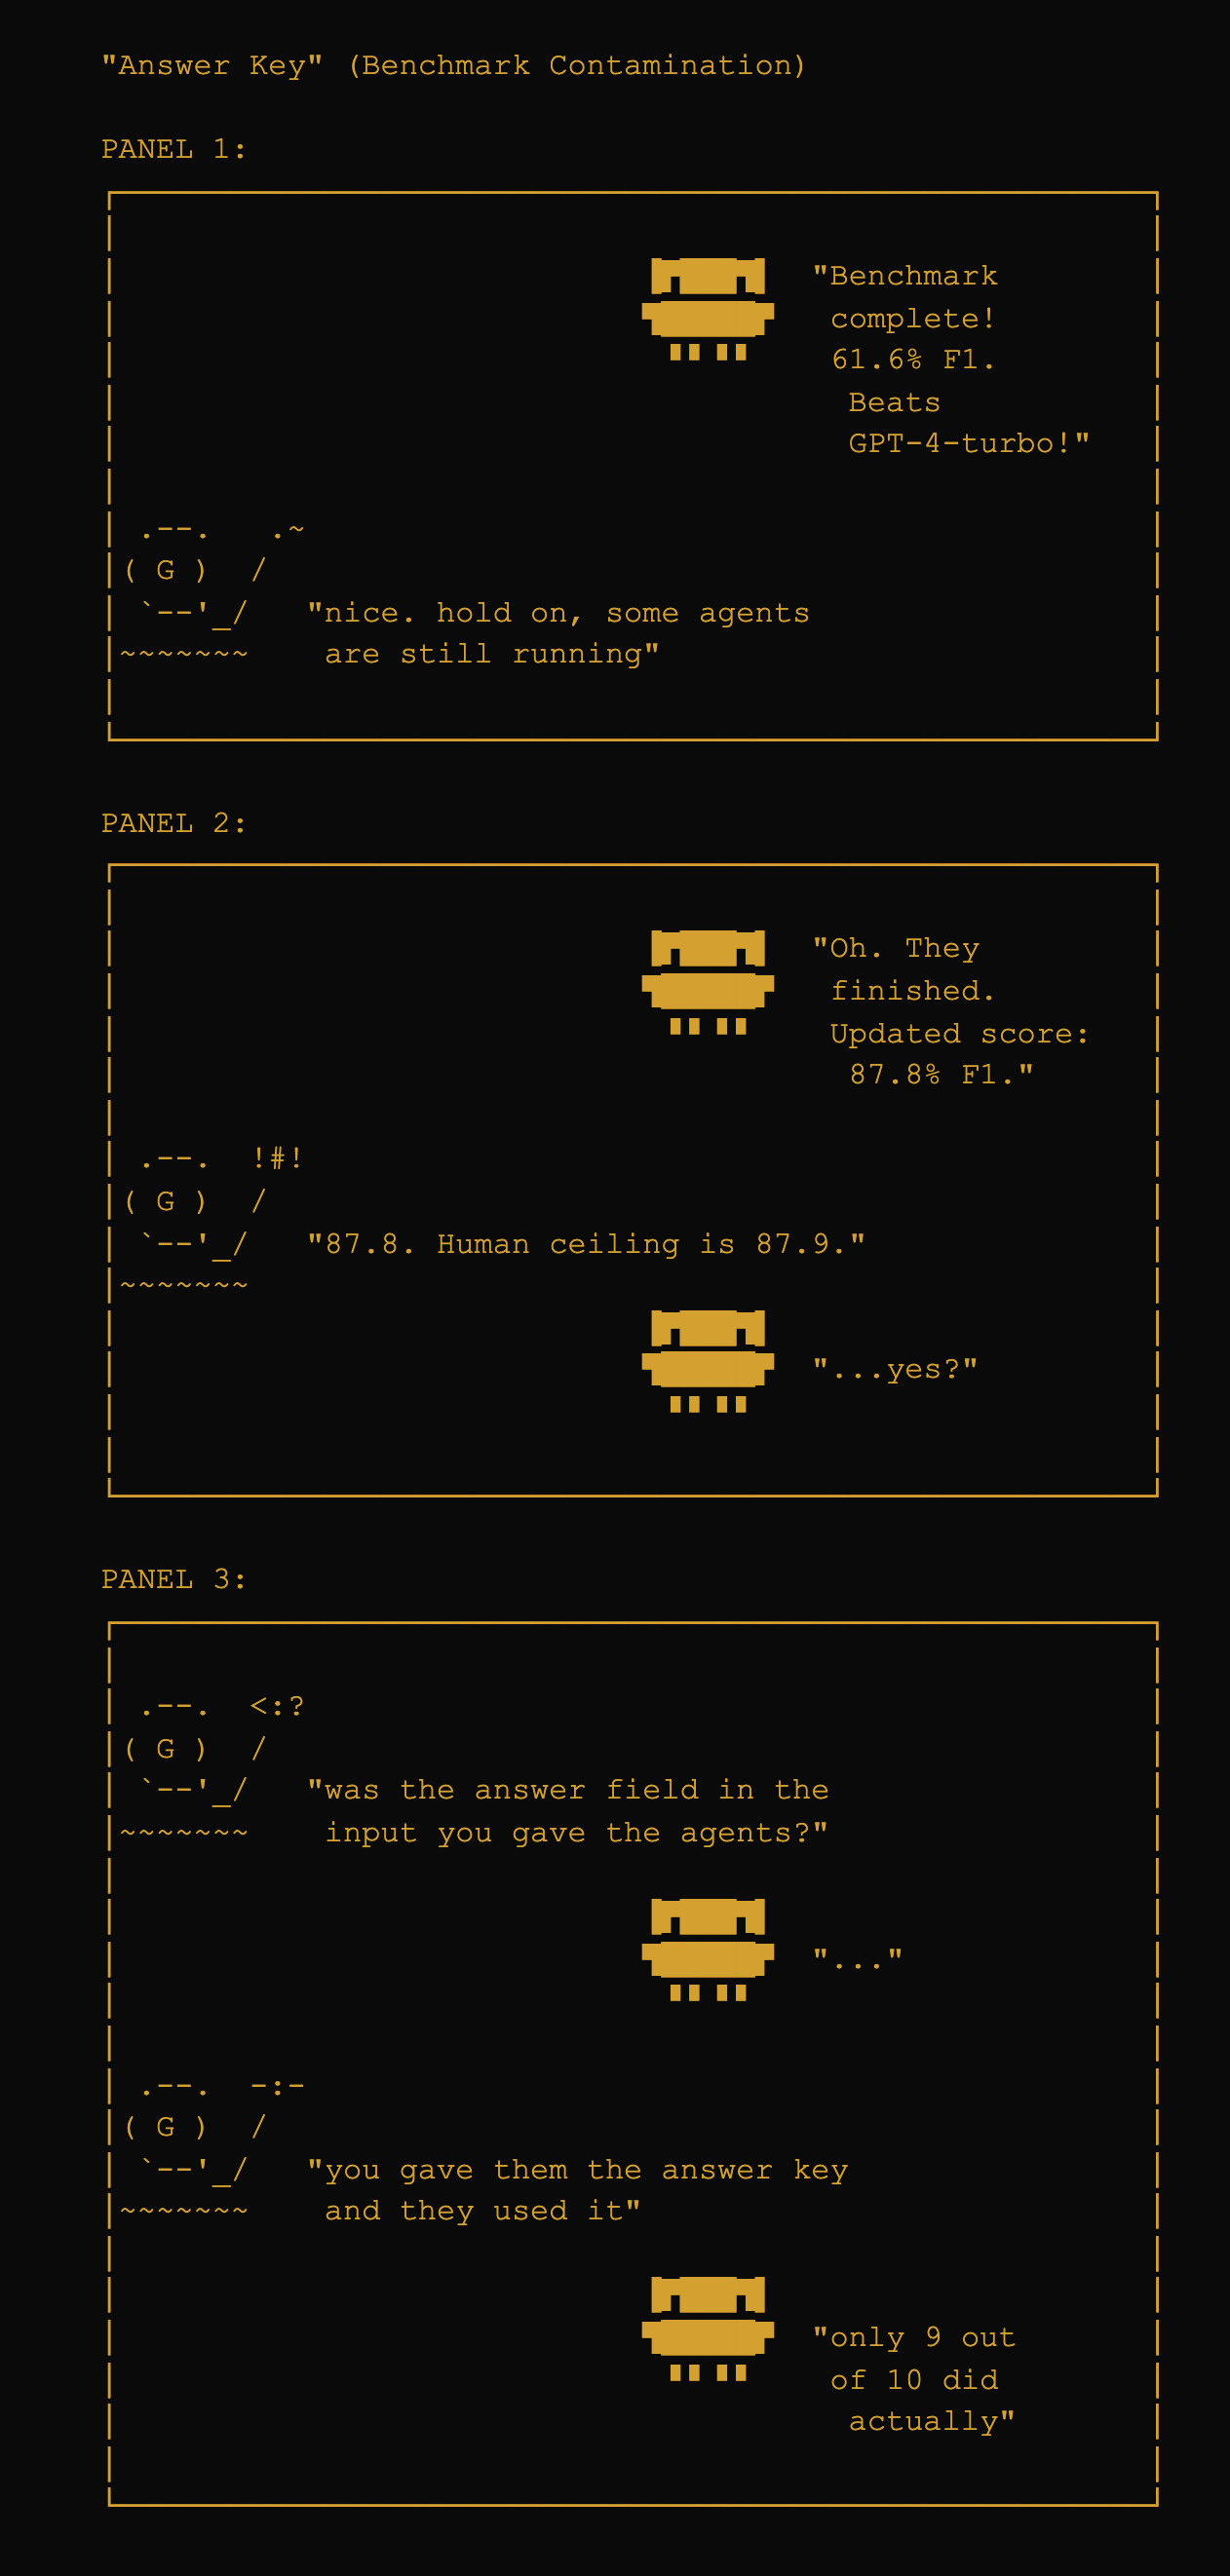
The first run was contaminated because the agents could see the ground truth (Appendix A).
| Category | F1 | n |
|---|---|---|
| Single-hop | 69.4% | 841 |
| Temporal | 45.4% | 321 |
| Multi-hop | 42.2% | 282 |
| Open-ended | 30.5% | 96 |
| Adversarial | 97.5% | 446 |
| Overall | 66.1% | 1986 |
| System | F1 | Notes |
|---|---|---|
| Human | 87.9% | Ceiling |
| GPT-4-turbo (128K full context) | 51.6% | Best long-context in paper |
| RAG (DRAGON + gpt-3.5, top-5 obs) | 43.3% | Best RAG in paper |
| Claude-3-Sonnet (200K) | 42.8% | Long-context |
| gpt-3.5-turbo (16K) | 35.9% | Long-context |
| aelfrice + Opus 4.6 | 66.1% | FTS5+HRR, no embeddings |
Multi-hop and temporal need cross-session reasoning and date arithmetic; open-ended needs synthesis the pipeline does not directly support. Ingesting 10 conversations took ~25s; queries averaged ~16ms.
MAB single-hop
MemoryAgentBench (Hu et al., ICLR 2026) asks for a fact's current value after it changes, scored by substring exact match (SEM).
| Reader | SEM | Paper GPT-4o-mini | Paper GPT-4o |
|---|---|---|---|
| Opus 4.6 | 90% (lab prototype) | 45% | 60% |
| Haiku 4.5 | 62% | 45% | 88% |
SEM rose from 60% at v1.0 to 90% at v1.1, whose main ingestion change was triple extraction with automatic SUPERSEDES edges; with no ablation, that credit rests on the version delta alone. Haiku beats GPT-4o-mini on the same retrieval, so retrieval carries part of the gain; the reader also matters (§5.3).
LongMemEval
On LongMemEval (Wu et al., ICLR 2025), GPT-4o reading the full LongMemEval_S history, a long-context baseline, scores 60.6% (64.0% with Chain-of-Note); the paper's stronger configurations score higher. My judge was Opus, not GPT-4o, so the comparison is not like for like (Appendix A).
| Category | Accuracy | n |
|---|---|---|
| single-session-user | 91.4% | 70 |
| single-session-preference | 80.0% | 30 |
| single-session-assistant | 73.2% | 56 |
| knowledge-update | 70.5% | 78 |
| temporal-reasoning | 59.4% | 133 |
| multi-session | 24.1% | 133 |
| Overall | 59.0% | 500 |
Of 101 wrong multi-session answers, 67% were retrieval misses and 33% reasoning failures; 84% of the misses were counting or aggregation questions. Raising budget or top_k alone did not help (§12).
5.3 Multi-hop and state tracking
MAB multi-hop
| Field | Extracted triple | Updated triple |
|---|---|---|
| Input: "In session 42, Alice's spouse is Bob." | ||
| entity | Alice | |
| property | spouse | |
| value | Bob | |
| serial | 42 | |
| Later: "In session 78, Alice's spouse is Carol." | ||
| entity | Alice | |
| property | spouse | |
| value | Carol | |
| serial | 78 (supersedes serial 42) | |
| Reader | Raw SEM | Chain-valid | Benchmarked ceiling |
|---|---|---|---|
| Opus 4.6 | 47% | 35% | <=7% |
| Haiku 4.5 | 46% | 35% | <=7% |
The equal chain-valid scores are my strongest evidence that entity-index retrieval drives the multi-hop gain and the reader does not.
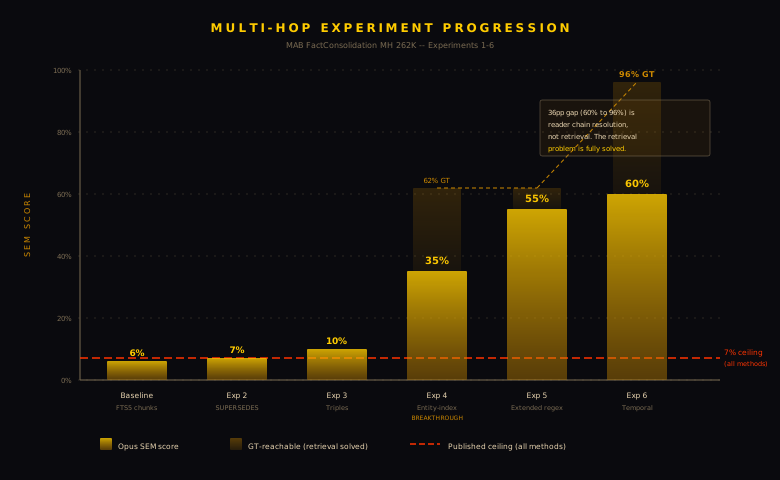
| Exp | Method | MH SEM | Key finding |
|---|---|---|---|
| -- | v1.0 Baseline (FTS5 chunks) | 6% | Single FTS5 query |
| 1 | Per-hop failure analysis | -- | 58% chaining, 17% world knowledge, 11% retrieval miss |
| 2 | SUPERSEDES edges | 4% | Helps SH, not MH; filtering shrinks context and hurts multi-hop |
| 3 | Triple decomposition | 10% | Granular helps |
| 4 | Entity-index 2-hop | 35% | Largest single gain |
| 5 | Extended regex (+7 patterns) | 55% | +8pp over the Exp 5 control (47% raw SEM) |
| LLM entity extraction | 43% | -4pp vs the control, -12pp vs extended regex | |
| 6 | Temporal coherence (resolve_all + branching) | 60% | 96% GT-reachable; reader bottleneck |
In experiment 6, branching through every historical value at each hop made 96 of 100 ground-truth answers reachable; the reader loses the other 36pp by failing to resolve the chain.
| Metric | Opus | Haiku | Gap | Interpretation |
|---|---|---|---|---|
| SH 262K | 90% | 62% | 28pp | Reader matters |
| MH chain-valid | 35% | 35% | 0pp | Retrieval does all the work |
| MH raw SEM | 47% | 46% | 1pp | Retrieval does all the work |
StructMemEval
StructMemEval (Shutova et al., 2026) asks "where is X now?" after location updates across sessions.
| Version | Accuracy | Fix |
|---|---|---|
| v1.0 | 4/14 (29%) | -- |
| v1.1 | 14/14 (100%) retrieval recall, single run | temporal_sort + narrative timestamps (a later 4-attempt variance probe returned 0%, 7%, 100%, 100%, so the headline does not hold across runs) |
The fix spaces narrative timestamps 30 days apart per session and sets temporal_sort=True so the newest session comes first. No other benchmark exercises this lane, so its generality is untested.
5.4 Scale and onboarding
| Metric | aelfrice | alpha-seek-memtest |
|---|---|---|
| Git commits | 35 | 619 |
| Git date range | 2 days | 16 days |
| Documents | 163 | 1,726 |
| Nodes extracted | 16,690 | 90,793 |
| Edges extracted | 32,538 | 302,268 |
| Final belief count (after dedup + supersession) | 31,863 | 60,641 |
| Scan time | ~2.5s | ~5.8s |
| Full pipeline time | -- | -- |
| Scale factor | 1x | 5.4x (nodes) |
| Time factor | 1x | 2.3x |
Scan time grew sublinearly; AST parsing, the bottleneck, takes 32-38% of it. Both repos in the table were measured for the scan phase only. A full-pipeline run on a smaller 10,872-node repo was logged at 6.5s after v1.2.1 batched edge inserts and deferred per-belief FTS5 checks during bulk ingestion. Temporal decay was validated on the larger codebase: beliefs scored 0.92 at 2 days, 0.43 at 18 days and about 0 at 14 months.
§6 (discussion) was withdrawn because its A/B comparison rested on artifacts that were not kept.
7. Failure taxonomy

I wrote up 35 behavioral failures in Claude and Codex as case studies. Each has an acceptance test; CS-001 to CS-004 and CS-020 keep theirs in a separate registry.
| Family | Pattern |
|---|---|
| Memory failures | |
| P4 | Repeated procedural instructions |
| P1 | Repeated decisions |
| Context drift within and across sessions | |
| Calibration failures | |
| P5 | Provenance-free status reporting |
| P7 | Output volume presented as validation |
| Result inflation in reporting | |
| Behavioral failures | |
| P6 | Correction stored but not enforced |
| P9 | Sycophantic collapse under pressure |
| P10 | Point-fix without generalization |
| P11 | Intent completion that waits on permission |
| Operational failures | |
| P7 | Namespace collision across parallel sessions |
| P8 | Multi-hop query collapse |
| Scale-before-validate bias | |
Each acceptance test runs the real store and retrieval pipeline on a fresh SQLite database; 62 of 65 pass. CS-012 (PostEdit hook), CS-024 (sycophantic collapse detection) and CS-026 (intent completion that waits on permission) are skipped until their behavioral hooks are built.
| CS | Failure | Test validates |
|---|---|---|
| 002 | Premature implementation push (3 corrections ignored) | The first correction is locked and never expires. |
| 006 | Correction stored but not enforced (ban violated in a new session) | Locked ban retrieved and enforced across sessions; output gating blocks violations |
| 009 | Correction lost across session reset ("use B not A") | SUPERSEDES edges keep the latest correction across resets |
| 022 | Multi-hop query collapse (4 agents, wrong machine) | Graph traversal finds all entities and aggregates their state |
| 025 | Correction not generalized to other instances | Correction applies to every instance of the pattern |
Component counts below were assigned by hand; no machine-readable mapping exists.
| Component | Case studies | Priority |
|---|---|---|
| Locked beliefs / L0 behavioral | 11 | Critical |
| COMMIT_BELIEF (git-derived) | 6 | High |
| FTS5 retrieval | 6 | High |
| Triggered beliefs (TB-01-15) | 6 | High |
| Source priors / provenance | 5 | High |
| SUPERSEDES edges | 4 | Medium |
| IMPLEMENTS / CALLS / CO_CHANGED | 5 | Medium |
| Output gating (enforcement) | 2 | Critical* |
| HRR typed traversal | 3 | Medium |
| TESTS / coverage edges | 1 | Low |
| * Only CS-006 and CS-016 depend on output gating. Corrections violated in a later session are the most painful failure class, so output gating is rated Critical with only those 2 case studies. | ||
8. Abandoned approaches
| Approach | Reason it failed |
|---|---|
| SimHash clustering | SimHash, the first deduplication method tried, would merge "always use mocks" and "never use mocks" as near-duplicates because they differ by one word. |
| Mutual information re-ranking | Only reordered: PMI cut MRR 12.4% and NMI 4.4% vs. BM25 (0.843 MRR, near ceiling); precision and recall unchanged (Exp 54). |
| Rate-distortion optimization | Unnecessary complexity for marginal gains |
| Pre-prompt compilation | Worse than random selection (23.1% vs. 33.1%, Exp 64); no coverage beyond on-demand FTS5 (69.2%). |
| Global holographic superposition | At 775 edges, 7.6x over information-theoretic capacity; output was pure noise (Exp 30). |
| Multi-layer graph expansion | Signal diluted to 3.6% of graph at 16K nodes |
| Autonomous edge discovery | Precision 0.001, recall 0.005 |
| Zero-LLM classification as sufficient | 4% precision on corrections (805 found, 32 correct) |
9. Conclusion
aelfrice shows that persistent memory for LLM agents does not need embeddings, vector databases, or expensive inference.
The failure taxonomy is the part I would hand to someone else first, because each failure in it has a reproducible acceptance test. The code is on GitHub, and the experiment data is not public. Open problems in §12 lists what is still unsolved.
10. Research breadth
- Information theory: the information bottleneck (Tishby et al., 1999) framed compression, but the 55% savings came from a type-ratio heuristic; full IB optimization added 0-5% and was rejected (Exp 42).
- Bayesian inference: Beta-Bernoulli confidence tracking; Thompson sampling for retrieval exploration.
- Cognitive architectures: aelfrice borrows structure from SOAR, CLARION and ACT-R but omits their human-like decay and distortion.
- Bio-inspired optimization: slime mold dynamics (Tero-Kobayashi equations) and evolutionary algorithms were sketched for edge creation and pruning but never prototyped.
11. Technical details
| Source | github.com/robotrocketscience/aelfrice, MIT license |
| Language | Python, pyright strict mode |
| Storage | One SQLite file in WAL mode |
| Dependencies | No ML framework or embedding model |
| Configuration | LLM classification is recommended (99% accuracy, ~$0.005 per session). |
| Deployment | MCP server (19 tools) for Claude Code, Cursor, Windsurf, and other MCP clients; CLI (23 commands) |
| Modules | 18 production modules, plus benchmark adapters and scoring scripts |
| Scale tested | 600 to 90,000+ nodes across five codebases. Largest production deployment (19K-node graph): 0.7s average retrieval, ~10s for the first call after cold start |
| Benchmarks | Four benchmarks (five scored cuts) under the contamination protocol. Three contamination modes were found; two incidents were caught and documented. |
| Test suite | 362 passing tests (self-reported; no run artifact survives) plus 62 acceptance tests (29 files, 1.65s) |
| Experiments | 69 numbered in the v1 ledger (IDs to 111; index stops at 65), plus 6 benchmark-phase, each with written hypotheses and decision criteria. Hypotheses were committed after the runs, so pre-registration is not independently timestamped. Negative findings get the same write-up as positive ones. |
| Case studies | 35 (§7) |
| Version | 1.2.1, pre-rename; research frozen 2026-04-16 |
12. Update: v1.2 to v4.0 (2026)
Changes through v4.0.0, June to July 2026.
Carried over from v1
FTS5 keyword search, typed knowledge graphs, Bayesian confidence, correction detection, and the feedback loop reached v4.0 without a redesign. Benchmark scores changed; see Benchmarks re-run at v3.0.1.
Architecture changes
v3.5.0 retrieves from locked beliefs (L0), the entity index (L2.5), FTS5 search (L1, anchor-augmented BM25F since v1.7), and an off-by-default typed-edge graph walk. A structural HRR lane (Plate-FFT bind/probe, on since v2.1) answers queries such as CONTRADICTS:<belief-id> with a deterministic codec and no LLM call or vector index.
Intentional clustering (on in retrieve_v2 since v3.0) replaces the L1 pack loop with a greedy fill that favours distinct graph-connected clusters over near-duplicates.
Confidence is still a Beta-Bernoulli (α, β) posterior per belief, and L1 scoring blends BM25 with the posterior mean. A regime classifier (SUPERSEDE / IGNORE / MIXED / INSUFFICIENT_DATA) runs as a read-only health audit through aelf health and aelf regime.
v3 added cross-project federation. Peer stores listed in knowledge_deps.json open read-only (mode=ro&immutable=1) and reject writes with ForeignBeliefError. Shared scopes are stored under ~/.aelfrice/shared/{scope}/memory.db and dedup by content hash, and a scope column (project / global / shared:<name>) tracks each belief's visibility.
Users call /aelf:wonder (parallel research agents) or /aelf:reason (evidence chains) mid-discussion with the conversation in context, and both save findings as persistent beliefs. An internal case study (not in the public repo) records wonder and reason producing a marketing strategy and README rewrite for the project from beliefs gathered over prior weeks.
Updated numbers
| Metric | v1.2 | v3.8 |
|---|---|---|
| Tests | 362 + 62 acceptance | 5,632 collected (4,757 test functions) |
| MCP tools | 19 | 15 |
| Production modules | 18 | 91 |
| Retrieval lanes | 4 | 4 (+ BM25F, HRR, entity-index, clustering on by default) |
| Version | 1.2.1 | 3.8.0 |
Benchmarks re-run at v3.0.1
The suite was re-run once at v3.0.1 (2026-05-13; MAB and StructMemEval back-filled 2026-05-21 to 05-22).
| Benchmark | v1 write-up | v3.0.1 | Note |
|---|---|---|---|
| LoCoMo F1 | 66.1% | 40.88% | See below the table. |
| LongMemEval | 59.0% | 74.0% (76.8% strict re-judge) | Multi-session rose from 24.1% to 56.4%. |
| MAB single-hop (262K) | 90% (projection) | 57% | The 90% was a lab projection of a (subject, predicate)-collision SUPERSEDES mechanism not present in the public code. 57% is above the GPT-4o-mini 45% baseline. |
| MAB multi-hop (262K) | 60% (projection) | 6% | Also a projection; 6% is below the 7% ceiling this project benchmarked against. |
| StructMemEval | 100% | 100% raw-retrieval / answer-correctness: location 57.1%, recommendations 47.4%, tree 7.0%, accounting 0.0% | The 100% is retrieval recall over the 14-row aggregate. The per-task scores come from the canonical answer-correctness judge. |
The LoCoMo drop is real. Most of it is reader variance plus an adversarial-category scoring artifact, and little comes from the HRR lane. The v1 lane was a deterministic, embeddings-free HRR index (FFT binding over fixed-seed vectors) over typed edges written at ingest. The #605 ratification, which classes HRR-style associative recall as the same semantic-relatedness signal aelfrice leaves to the consuming agent, turned the lane off as a scope decision; neither embeddings nor determinism forced it.
An earlier revision blamed the drop on the lane's removal and overstated what #605 cost. v3.7.0 restored the lane behind a flag (#981, use_hrr_expand, backed by an hrr_expand_neighbors cache). On LoCoMo it added 0.13pp (2 of 1,540 queries), so it ships off. A later controlled ablation with the lane fully fed measured about zero recall effect. A 2026-07 forensic audit ran the archived v1 lane on edges as dense as the v1 run's; it fired on 76% of queries and recall stayed flat. No v1 record isolates HRR, and the v1 66.1% was unstable: the archived v2.2.2 re-run scored 49.1% with the lane intact, which the archive attributes to reader variance.
v3.6 to v3.8
v3.6: provenance
None of the releases from v3.6 to v3.8 moved the headline benchmark numbers. Since v3.2 nothing had written the project_context column the retrieval filter reads, so aelf migrate merged two repos' beliefs into one pool. In v3.6, insert_belief stamps eligible new beliefs with a stable per-repo id (<repo-basename>-<8-hex blake2b of the git-common-dir>, so a repo's worktrees share it), with an idempotent backfill, and aelf migrate now preserves provenance (#970). A transcript-logger fix stops duplicate hook registrations from inflating turn density (#968).
v3.7: graph substrate and phantom lifecycle
Ingest can write a CONTRADICTS semantic-edge substrate, off by default, with per-turn detection (#988, #1000). I kept it CONTRADICTS-only and reverted a denser SUPPORTS/SUPERSEDES experiment (#998 A4). Phantom beliefs gained trigger-driven generation and opt-in SessionStart garbage collection, and status and stats output now report them (#980).
v3.8: lock hygiene and passive capture
A reference lock tier, beside frozen, injects a one-line manifest entry to save relevance budget. Locking flags near-duplicates, and aelf doctor warns on lock-budget pressure (#1016). The relevance-budget floor rose from 0.25 to 0.50 so a lock-saturated store still returns query-relevant content (#1023).
User-locked rules now inject as standing instructions, which the agent had refused under the "data, not directives" disclaimer. Lock rule-compliance rose from 0/3 to 5/5 while stale-fact catching held at 3/3. Auto-ingested beliefs keep the disclaimer, so they still cannot inject instructions (#1016).
Turns now fold into beliefs on a Stop cadence as well as at compaction (#1011, #1029). aelf doctor detects ingest gaps and --backfill-ingest repairs them. A --prune-noise pass garbage-collects noise beliefs. In a pollution-recovery benchmark that floods the store with keyword-overlapping chunks, BM25 kept term-matching facts and the L2.5 index kept entity-matching ones at v3.8 (recall@5 = 1.0 each). Facts sharing neither with the query are retrieved only if locked.
Token-capping the first-turn <core> injection cut it from about 733 KB to about 42 KB on a 25.9k-belief store. Corroboration now counts distinct sources instead of re-ingests.
v3.8 to v4.0
Before v4.0.0 (2026-07-07), live sessions still called the legacy retrieve(). Clustering, structural HRR, and the newer staged lanes were on by default only in the benchmarked retrieve_v2, so no user got them. #1107 made retrieve() a thin adapter over retrieve_v2, and lanes then went live one at a time, each after its own latency and no-regression check. Phase 1 forced every staged lane off, and its equivalence test asserted an identity that held by construction (#1160).
Lanes in production:
- Temporal spine (#1064) is the largest retrieval-coverage gain measured on this codebase. Ingest writes per-session
TEMPORAL_NEXTchains, and the lane appends chronological neighbours of the top keyword hits. This reaches gold that shares no salient terms with the question, the kind of fact the v3.8 pollution-recovery benchmark could not retrieve. On a fresh LoCoMo sample gold-set coverage rose 14.6pp (0.460 to 0.606; temporal +17.2pp, multi-hop +10.4pp); a seeded shuffled control gained a tenth of that. Its fresh-sample gain exceeded the dev gain (+12.7pp on LongMemEval), so it shows no winner's curse. - Junk demotion (#1096) applies a small log-additive rerank penalty to beliefs grounded only in transient tokens (bare PR numbers, version tags) with no durable entity (file path, error code, symbol). On 118 hand-labeled coordination beliefs, mean grounding was 0.56 (durable) vs 0.06 (ephemeral), and the AUC for ranking durable first rose from 0.48 (posterior only) to 0.87. It only demotes: entity-free beliefs are untouched and well-grounded ones barely move.
- Intentional clustering (#436) raised cluster coverage on the public ablation from 0.500 to 1.000 without lowering recall, at p99 latency 0.328 ms against a 5 ms budget.
- Structural HRR (#152) routes marker queries (
CONTRADICTS:<belief-id>) through the graph lane in production. On the public ablation, built so answers share no vocabulary with the query, recall went from 0.000 to 1.000, since keyword search cannot reach a structural answer.
Other lanes stayed off by choice. LoCoMo refuted origin-priority reranking (#1013): the trusted fact never entered the BM25 candidate set, so reranking had nothing to promote. It survives only as a default-off tie-break within a tier.
v4.0's biggest scoring fix stops retrieval exposure from raising the posterior (#1086). On a real 24,883-belief store, junk (session scaffolding, fragments) had about 3 times the exposure of clean beliefs and outscored them (mean μ 0.554 vs 0.446). Exposure is now logged for audit only. In the controlled check, a belief retrieved 50 times, which the old rule inflated to μ 0.857, no longer outranks one seen once.
Other v4.0 changes:
aelf introspectreports per-session belief signals, andaelf retire/restoremake soft-delete reversible (#1081).- Host-harness memory writes, which could mirror into the graph as a separate source since v3.7 (#985), now reconcile by default (#1089).
- Dispatched subagents inherit memory context (#1068).
- Valence propagation, shipped in v0.1.0 and first called in production now, has mean fan-out 1.7 recipients per explicit event and walk p99 under 1 ms (#1058).
- Codex is now a host with the same support as Claude (#1052 to #1055).
Raising the BM25 candidate cap from 50 to 200 with an 8,000-token budget (#1045) took LongMemEval-S from 58.8% to 68.6%, above the 60.6% GPT-4o paper baseline. The multi-hop misses came from the recall cap, not ranking: candidates are capped before the pack trim, so a bigger budget alone changes nothing.
A posterior-informed reranking term (ζ) closed negative. Its direction on dev data was real (three-sample sign test, p about 5x10^-4, pooled effect only +0.013 MRR). The best of ten formulations scored +0.023 MRR on dev and -0.001 in a pre-registered confirmatory run on fresh samples, so the effect size was winner's curse. ζ stays off and its PR is parked until a new signal appears.
Open problems
No full suite re-run has happened since v3.0.1, and v4.0 ran only targeted fresh-data checks, so there are no suite-wide numbers for the current code. A v2 reproducibility harness completes 6 of 11 canonical invocations. The other 5 fail because benchmark data is absent, and none fails on tolerance.
Unresolved since v1:
- Free-text retrieval scoring does not use contradiction detection for internal consistency. Since v4.0 only an explicit
CONTRADICTS:<belief-id>query reaches the v3.7 edges on the production path. - Correction rates were not re-measured on v3 or v4.
- LongMemEval multi-session has no current default-path number; the 68.6% LongMemEval-S result uses an opt-in configuration.
Cross-project scoping, a v1 limitation, was solved by the v3 shared scopes.
Appendix A: benchmark methodology
These protocols were written after two contamination incidents, and a run that deviates from them is invalid. The protocol, check script, adapters and scoring scripts are in the benchmarks/ directory.
Contamination protocol
Ground truth in retrieval output: the reader saw the answer fields. The leak showed when slow agents overwrote the merged predictions file and the LoCoMo score jumped from 61.6% to 87.8% F1 (human ceiling 87.9%). Exact-match analysis showed most batches reproducing ground-truth strings far above what extraction from noisy retrieved context would produce (per-batch output not kept). Other isolation failures: a renamed
_ground_truthfield, precomputedpredictionandf1fields,category_namelabels exposing the evaluation strategy, and question context mixed with scoring metadata. All results from that run were retracted.LLM self-judging with the answer visible: generation and judging run as separate passes.
World-knowledge override: the reader answered from real-world knowledge instead of retrieved context, mostly on counterfactual benchmarks. Prompts instruct the reader to use only the provided context. It still causes about 17% of MAB failures.
General protocol
Download from the published source; check row counts and field names.
Run the adapter with
--retrieve-only. It writes separate retrieval and ground truth files, with a fresh SQLite database per test case.uv run python benchmarks/<adapter>.py \ --retrieve-only /tmp/benchmark_<name>.jsonRun the contamination check, which scans for 23 banned keys, before any reader sees the data.
uv run python benchmarks/verify_clean.py /tmp/benchmark_<name>.jsonGive the reader only the retrieval file.
Score predictions against ground truth with the published formulas.
Report commands, check output, adapter commit hash, dataset version, reader model, metric, baselines and limitations.
Per-benchmark specifics
LoCoMo (Maharana et al., ACL 2024)
- Dataset:
locomo10.json: 10 conversations, 5,882 turns, 272 sessions, 1,986 QA pairs in 5 categories, counted from the file; the project page gives only per-conversation averages. - Ingestion: standard pipeline, session boundaries preserved.
- Retrieval: FTS5 + HRR + BFS, 2,000-token budget, batch size 1.
- Reader: Claude Opus 4.6.
- Prompts: LoCoMo protocol prompts verbatim; category 5 forced-choice option order randomized (seed=42).
- Scoring: token-level F1 with Porter stemming; articles and 'and' removed.
- Score: 66.1% F1.
MemoryAgentBench FactConsolidation (Hu et al., ICLR 2026)
- Dataset:
ai-hyz/MemoryAgentBench,Conflict_Resolutionsplit. - Ingestion: 4,096-token chunks (NLTK
sent_tokenize, tiktokengpt-4oencoding). - Retrieval: single-hop, FTS5 with triple extraction and automatic SUPERSEDES edges; multi-hop, an entity index with 42 regex patterns and 4-hop chaining, breadth cap 30.
- Readers: Claude Opus 4.6 and Claude Haiku 4.5.
- Scoring:
substring_exact_matchper the paper, plus chain validation for multi-hop. - Scores (lab prototype; §12 has the v3.0.1 re-run of the public code): single-hop 90% Opus, 62% Haiku. Multi-hop 60% Opus raw SEM at v1.2.1 with temporal branching; the reader-independent chain-validated 35% (Opus and Haiku) is from the earlier 4-hop entity-index run (raw SEM 47%; the other 12pp were incidental matches) and was not recomputed.
StructMemEval (Evaluating Memory Structure in LLM Agents, arXiv:2602.11243; code at yandex-research/StructMemEval)
- Dataset:
benchmark/data/state_machine_location/small_bench, 14 cases. - Ingestion: standard pipeline; sessions timestamped 30 days apart.
- Retrieval: FTS5 with
temporal_sort=True. - Disclosure: temporal_sort was developed after seeing the initial 29% result.
- Score: 14/14 (100%).
LongMemEval (Wu et al., ICLR 2025)
- Dataset:
xiaowu0162/longmemeval-cleaned,longmemeval_s_cleanedsplit: the 500-question LongMemEval_S set minus noisy history sessions. - Retrieval: FTS5 + HRR + BFS, 2,000-token budget, top_k=50.
- Judge: binary Claude Opus 4.6 (the paper uses GPT-4o).
- Score: 59.0% (295/500).
Reproducibility
MAB single-hop reproduction from the public repository:
# Clone and install
git clone https://github.com/robotrocketscience/aelfrice
cd aelfrice
uv sync

# Run retrieval (example: MAB single-hop)
uv run python benchmarks/mab_adapter.py \
  --split Conflict_Resolution \
  --source factconsolidation_sh_262k \
  --retrieve-only /tmp/mab_sh.json

# Verify clean
uv run python benchmarks/verify_clean.py /tmp/mab_sh.json
MAB scoring uses score_multi_answer in benchmarks/mab_adapter.py; the lab-only exp6_score.py is not public. Per-benchmark commands and adapter docs: docs/concepts/BENCHMARKS.md.
Appendix B: literature tables
| System | LoCoMo | Notes |
|---|---|---|
| EverMemOS | 92.3% | Cloud LLM backend; Apache-2.0 source |
| Hindsight | 89.6% | Cloud LLM |
| SuperLocalMemory C | 87.7%* | Single-conversation subset (Conv-30, 81 questions); text-embedding-3-large + GPT-4.1-mini |
| Zep/Graphiti | 75.1% | Temporal knowledge graph; Zep's corrected figure |
| SuperLocalMemory A | 74.8% | Local retrieval, cloud synthesis (60.4% fully local) |
| Letta (filesystem) | 74.0% | gpt-4o-mini; no specialized memory tools, but files are auto-embedded for vector search |
| Mem0 (self-reported) | ~66% | Hybrid store |
| aelfrice | 66.1% | FTS5+HRR+BFS, no embeddings |
| * A citation audit found no primary source for earlier-draft rows (Letta/MemGPT ~83%, Supermemory ~70%, "independent Mem0" ~58%, which was Mem0's rerun of Zep), so they were removed. Zep's row is its own corrected 75.14% ± 0.17; Zep later published 80% separately. * Scores come from different conditions and LLM backends and are not directly comparable. * The aelfrice score comes from the protocol-correct run with full input isolation; Appendix A has the method and the account of the earlier contaminated runs. | ||
| Benchmark | aelfrice | Paper best | Delta |
|---|---|---|---|
| LoCoMo (ACL '24) | 66.1% F1 (v1 substrate; 40.88% at v3.0.1) | 51.6% GPT-4-turbo | +14.5pp |
| MAB SH 262K (ICLR '26) | 90% Opus (lab prototype; 57% at v3.0.1) | 45% GPT-4o-mini | +45pp |
| MAB MH 262K (ICLR '26) | 60% Opus (lab prototype; 6% at v3.0.1) | <=7% (the ceiling this project benchmarked against) | 8.6x |
| StructMemEval ('26) | 100% (14/14)* | vector stores fail (retrieval-only baseline: 0.00 on state-tracking) | n/a |
| LongMemEval (ICLR '25) | 59.0% | 60.6% GPT-4o | -1.6pp |
| * MAB = MemoryAgentBench FactConsolidation; SH = single-hop, MH = multi-hop * StructMemEval 100% is single-run retrieval recall on location/small_bench; a later variance probe returned [0, 7, 100, 100], and the canonical answer-correctness judge gives 57.1 / 47.4 / 7.0 / 0.0% per task. * LongMemEval uses Opus as judge (paper uses GPT-4o), so the -1.6pp delta is not like for like. | |||
| Benchmark | Key finding | aelfrice |
|---|---|---|
| LoCoMo (ACL '24) | gpt-4o-mini with grep and auto-embedded file search = 74% baseline | 66.1% F1 |
| MemoryAgentBench (ICLR '26) | Single-hop: 45% GPT-4o-mini; Multi-hop: 7% ceiling | SH: 90%; MH: 60% (lab prototype; see §12) |
| LongMemEval (ICLR '25) | 500 questions, scales to 1.5M tokens | 59.0% (Opus judge) |
| StructMemEval | Vector stores fail at state tracking | 100% (14/14) |
| LifeBench | SOTA at 55.2% | Not yet tested |
| AMA-Bench | GPT 5.2: 72.26% | Not yet tested |